Base Platform  /  Code Snippet Archive

Code Snippet & Reference Library

Battle-tested, copy-pasteable snippets across PHP, Python, JavaScript, VB.NET, SQL and Bash — compiled from real SaaS engineering sessions.

469
Snippets Indexed
2
PHP
0
JavaScript
7
Python

Showing 469 snippets

SNP-2025-0016 Tech 2026-04-28

Getting Started with Netlify Deployment

▾
THE PROBLEM

Netlify is a powerful deployment platform known for its speed, reliability, and seamless integration with version control systems like GitHub. It supports hosting static files, static site generators, and serverless functions.

  1. Visit Netlify.
  2. Click on "Sign Up" to create a new account.
  3. You can sign up using your GitHub account or provide the required information to create a new Netlify account.
Import from GIT
  1. After creating an account, log in to your Netlify dashboard.
  2. Click on the "New site from Git" button.
  3. Choose GitHub as the continuous deployment source.
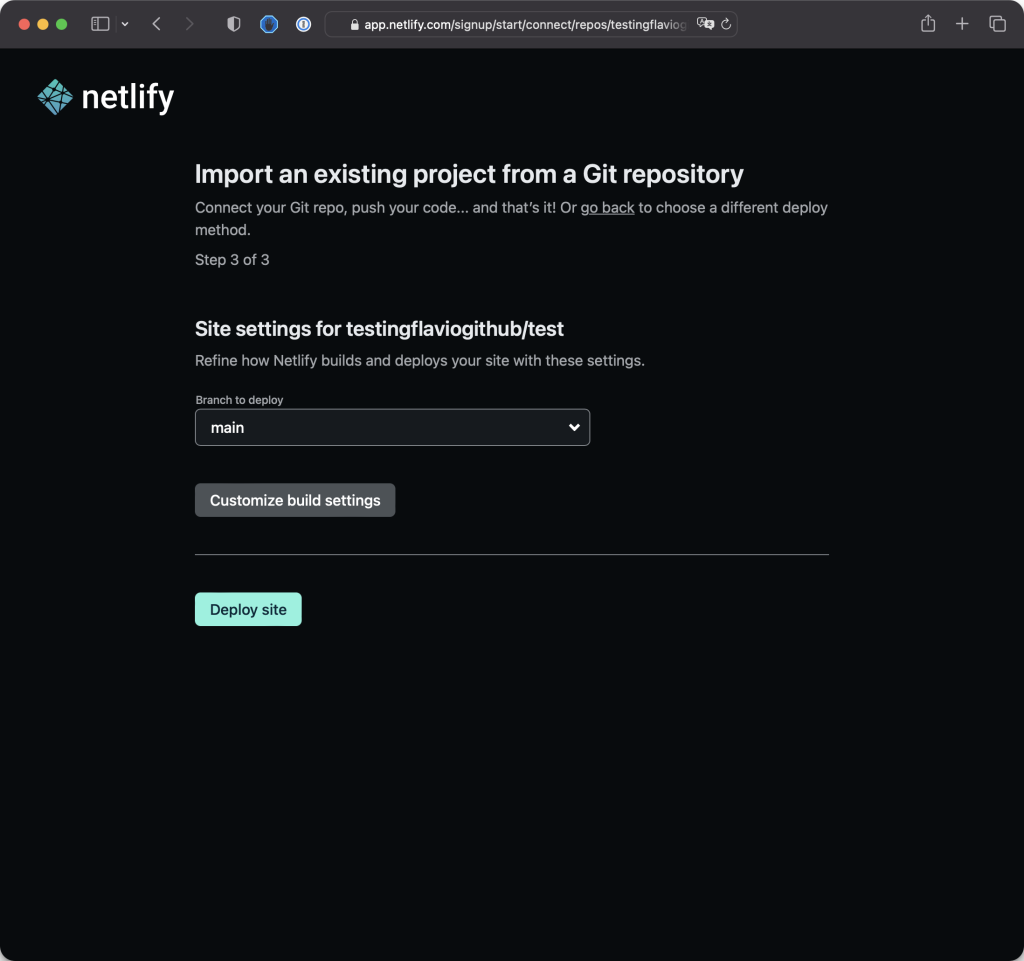
  1. Select the repository you want to deploy.
  2. Configure your build settings. For a simple HTML site, the default settings should work.
  3. Click on the "Deploy site" button.
  1. Clone your GitHub repository to your local machine.
  2. Make changes to your HTML files or any other assets.
  3. Commit and push the changes to your GitHub repository.
  4. Netlify will automatically detect the changes and redeploy your site.
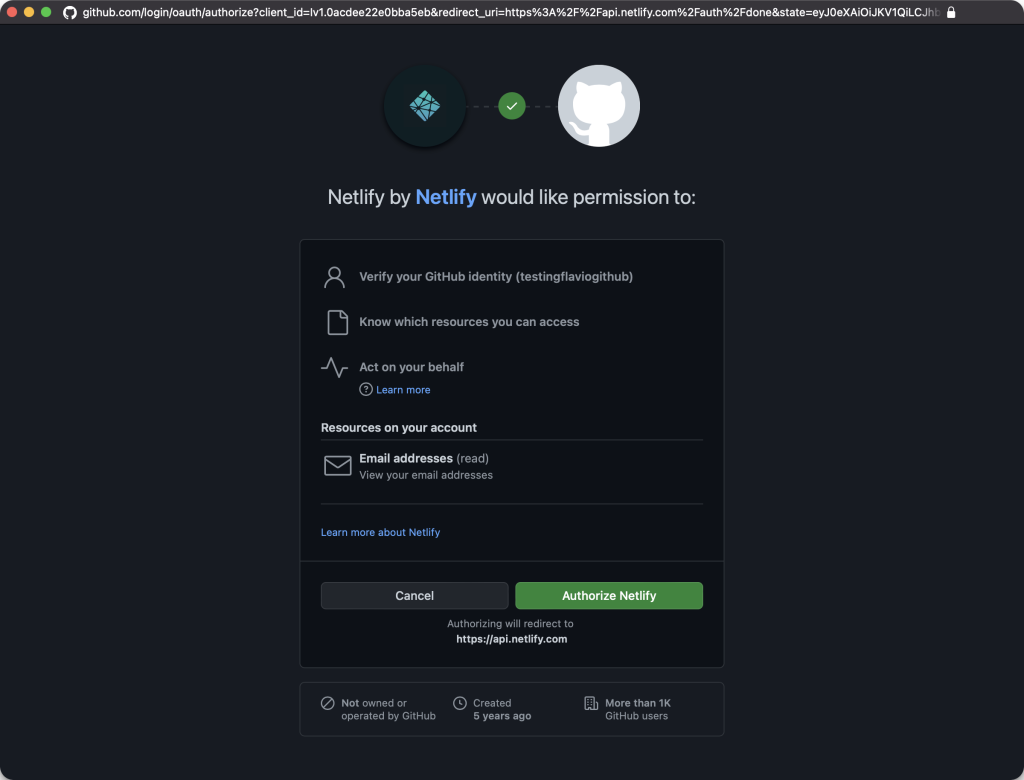
Allow Netlify Permissions
  1. Go back to your Netlify dashboard.
  2. You'll see a new deployment triggered by your recent push.
  3. Once the deployment is complete, you can visit the provided Netlify URL to view your live site.
  • Netlify provides features like custom domains, serverless functions, and more. Explore the settings in your Netlify dashboard to customize your deployment.
  • For advanced projects, you can explore static site generators like Hugo or Gatsby and leverage Netlify's features for a seamless deployment pipeline.

By following these steps, you'll be able to deploy and update your website with ease using Netlify. Feel free to explore more features offered by Netlify to enhance your web development workflow. Happy coding!

Open Full Snippet Page ↗
SNP-2025-0009 Tech 2026-04-28

HTTP, Web Browsers, and Web Servers

▾
THE PROBLEM

Think of the internet as a vast phone network infrastructure, with numerous interconnected devices, each assigned a unique identifier, much like a phone number. But what makes the internet truly powerful is its applications, and over time, various attempts have been made to explore its potential.

Early internet endeavors, like email and Usenet newsgroups, made their mark, but it was the World Wide Web that truly revolutionized our online experiences.

The inception of the World Wide Web can be credited to Sir Tim Berners-Lee, a visionary based in Switzerland. Back in the early days, he conceptualized a utility to visualize and interlink research papers. Little did he know that this idea would evolve into the World Wide Web we know today.

Working at CERN in Geneva, Berners-Lee introduced the concept of "hyperlinks." This innovative idea involved linking documents together, allowing users to navigate seamlessly between them. His creation was initially an academic tool, but its impact was far-reaching.

At the heart of the web's functionality is HTTP, or Hyper Text Transfer Protocol. This protocol, operating on top of TCP (Transmission Control Protocol), dictates how web browsers communicate with web servers and vice versa. It sets the rules for the exchange of information between these entities.

In the web ecosystem, two primary players come into play: the Web Server and the Web Browser. The Web Server, typically hosted remotely, serves web pages to clients, which are the Web Browsers. The interaction between these components is governed by the rules established by HTTP.

Imagine the Web Server as a repository of web pages, and the Web Browser as the tool that fetches and displays these pages for users. The communication between them is akin to a conversation following the rules of the HTTP protocol.

Web pages, the visual entities we interact with, are essentially text files encoded in HTML, or Hyper Text Markup Language. HTML provides the structure and format for web content, defining elements like paragraphs, headings, images, and more.

As we journey further into understanding the web, we'll delve into HTML and explore how these text files become the immersive web pages we encounter daily. Stay tuned as we bridge the gap between theory and practical implementation in the realm of HTML.

Open Full Snippet Page ↗
SNP-2025-0378 Julia code examples Julia programming 2026-04-27

How Can You Leverage Julia's Metaprogramming Features for Advanced Development?

▾
THE PROBLEM

In recent years, Julia has emerged as a powerful language particularly for numerical and scientific computing. However, one of its most intriguing features lies in its metaprogramming capabilities. Metaprogramming allows developers to write programs that manipulate other programs, enabling a level of flexibility and dynamism that can be a game-changer for complex applications. Understanding how to effectively leverage Julia's metaprogramming features can significantly enhance your development process, allowing for cleaner code, reduced boilerplate, and greater adaptability in your applications. In this post, we will explore the intricacies of Julia's metaprogramming, provide practical examples, and discuss best practices to effectively harness these features.

Metaprogramming is the practice of writing programs that can generate, analyze, or transform other programs. In Julia, metaprogramming is primarily achieved through macros, code generation, and introspection. This allows developers to create highly reusable and generic code structures that adapt based on runtime conditions or compile-time evaluations. Understanding metaprogramming is essential for any advanced developer looking to push the limits of what can be achieved in Julia.

Julia was designed from the ground up to be a high-performance language that combines the best features of dynamic languages with the speed of statically typed languages. This design philosophy extends to its metaprogramming capabilities. While traditional languages like Lisp and Ruby have long been known for their metaprogramming features, Julia's approach offers a unique blend of performance and flexibility, making it especially attractive for scientific computing and data analysis.

At the heart of Julia's metaprogramming are macros. Macros allow you to transform code before it's executed. Unlike functions, which operate on values, macros operate on the code itself. This means they can be used to generate code dynamically or to modify existing code structures.

Key Concept: Macros are defined using the @ symbol followed by the macro name. They take in expressions and return modified expressions.

Here's a simple example of a macro that logs the time taken to execute a block of code:


macro timeit(expr)
    return :(begin
        local start_time = time()
        $expr
        local end_time = time()
        println("Execution time: ", end_time - start_time, " seconds.")
    end)
end

Creating a macro in Julia involves defining a function that returns an expression. The returned expression is then evaluated in the context where the macro is called. This allows for powerful code generation capabilities. Below is a more advanced example of a macro that can create a simple getter and setter for a specified variable:


macro generate_getter_setter(var_name)
    quote
        function get_$(var_name)()
            return $(esc(var_name))
        end

        function set_$(var_name)(value)
            $(esc(var_name)) = value
        end
    end
end

When you call this macro with a variable name, it will generate a getter and setter for that variable, which can be extremely useful for managing state in larger applications.

In addition to macros, Julia supports code generation through functions that return expressions. This can be beneficial when you want to create code dynamically based on certain parameters or conditions. For instance, if you need to generate a function that performs a specific operation based on an input integer, you can do so as follows:


function generate_function(n)
    return :(function f(x)
        return $(Expr(:call, Symbol("op$n"), x))
    end)
end

This function returns an expression that defines another function based on the operation specified by the integer. This level of dynamic function generation can lead to highly efficient code structures.

Introspection is another crucial aspect of metaprogramming in Julia. It allows you to inspect the properties of types and methods at runtime. This can be particularly useful for debugging or for implementing features such as automatic method dispatch based on the types of inputs. For example, you can use the `methods` function to retrieve all methods associated with a given function:


methods(+, Tuple{Int, Int}) # Lists all methods for the addition operator for integers

By utilizing introspection, you can build more robust and flexible applications that can adapt to varying types and structures without requiring extensive modifications to your codebase.

To effectively utilize metaprogramming in Julia, consider the following best practices:

  • Keep It Simple: Use metaprogramming to reduce boilerplate, but avoid making your code unnecessarily complex.
  • Document Your Code: Since metaprogramming can obfuscate the flow of your program, ensure that all macros and generated code are well-documented.
  • Test Extensively: Implement unit tests for any macros or dynamically generated code to verify their correctness.
  • Profile Performance: Always profile your code to understand the performance implications of using metaprogramming techniques, ensuring you're not introducing bottlenecks.

1. What are the main advantages of using macros in Julia?

Macros allow for code generation and transformation at compile time, reducing boilerplate and enhancing performance. They can also facilitate domain-specific languages (DSLs) within Julia.

2. Can metaprogramming slow down my application?

Yes, if not used carefully. It’s essential to profile your application to identify any performance bottlenecks introduced by metaprogramming.

3. How do I debug macros in Julia?

Debugging macros can be challenging. Use the `@show` macro to inspect the output of your macro before it gets executed. Also, consider using the Julia REPL for interactive testing of your macros.

4. Are there any built-in macros in Julia?

Yes, Julia comes with several built-in macros like `@time`, `@code_warntype`, and `@generated`. These can help you profile your code and understand its performance characteristics better.

5. Is there a learning curve for metaprogramming in Julia?

While the concepts are powerful, they can be complex. It’s advisable to start with simpler macros before moving on to more intricate metaprogramming tasks.

Julia's metaprogramming features provide developers with a robust toolkit for creating dynamic, adaptable, and efficient applications. By understanding macros, code generation, and introspection, you can significantly enhance your coding practices and reduce boilerplate. However, it is crucial to use these features judiciously, ensuring that your code remains readable and maintainable. As you embark on your journey with Julia, remember to document your code, test thoroughly, and profile performance to fully leverage the power of metaprogramming. With these tools at your disposal, you're well-equipped to tackle complex programming challenges in Julia.
PRODUCTION-READY SNIPPET

While metaprogramming offers incredible power, it also comes with its own set of challenges. Here are some common pitfalls and their solutions:

Pitfall 1: Overusing Macros

Macros are powerful, but overusing them can lead to code that is difficult to read and maintain. Use them judiciously and prefer functions for simpler tasks.

Pitfall 2: Code Complexity

Generated code can sometimes be hard to understand. Always provide documentation and comments to explain the purpose of generated code.

Pitfall 3: Performance Overhead

Dynamic code generation can introduce performance overhead. Profile your code to ensure that the benefits of metaprogramming outweigh the costs.

REAL-WORLD USAGE EXAMPLE

Metaprogramming in Julia has real-world applications across various domains, including:

  • Scientific Computing: Dynamically generating functions for numerical methods based on the type of data being processed.
  • Machine Learning: Automatically creating models and pipelines based on user input or data characteristics.
  • Data Manipulation: Generating custom data transformations based on meta-information from datasets.

These applications highlight the versatility of Julia's metaprogramming capabilities, allowing for enhanced productivity and cleaner code in complex projects.

Open Full Snippet Page ↗
SNP-2025-0342 Gradle code examples Gradle programming 2026-04-27

How Can You Leverage Gradle's Build Cache for Enhanced Performance in Large Projects?

▾
THE PROBLEM

In modern software development, the efficiency of the build process can significantly impact productivity. Gradle, a powerful build automation tool, offers features like the build cache that can dramatically enhance performance, particularly in large projects. Understanding how to leverage Gradle's build cache is essential for developers who want to optimize their build times and streamline their workflows. In this post, we will explore the intricacies of Gradle’s build cache, its benefits, and how to implement it effectively.

The build cache in Gradle is a mechanism that stores the outputs of build tasks, allowing them to be reused in subsequent builds. This is particularly beneficial when working on large projects or teams, where multiple developers might be building the same codebase repeatedly. The build cache can be local (on your machine) or remote (shared among team members), and it significantly reduces the time required to build your project by avoiding unnecessary recompilation of unchanged code.

💡 Key Benefit: Using the build cache can reduce build times by up to 90% in some scenarios, providing a tremendous boost to developer productivity.

Enabling the build cache in Gradle is straightforward. You simply need to modify your settings.gradle file to include the build cache configuration. Here’s how to do it:

buildCache {
    local {
        enabled = true
    }
    remote(HttpBuildCache) {
        url = 'https://my-build-cache-server/cache/'
        enabled = true
    }
}

In the example above, we enabled both local and remote build caches. The remote cache requires a correctly configured server, which we will discuss later in this post.

Gradle uses cache keys to determine if a task's outputs can be reused. Cache keys are generated based on the task's inputs, including the source files, properties, and environment variables. If none of these inputs have changed since the last build, Gradle will reuse the cached output instead of executing the task again, thus saving time.

✅ Best Practice: Always ensure that your tasks are configured correctly so that Gradle can compute the cache keys accurately. This includes avoiding side effects in tasks that might alter inputs.

Not all tasks are cacheable by default. To make a task cacheable, you should define its inputs and outputs explicitly. Here’s an example of a custom task configured for caching:

task myTask {
    inputs.file('src/main/resources/config.txt')
    outputs.file('build/output.txt')

    doLast {
        // Task logic here
        println 'Task executed'
    }
}

In this example, the task myTask declares its input and output, allowing Gradle to determine if it needs to be executed or can use a cached output.

For teams working in a collaborative environment, a remote build cache can be a game changer. It allows developers to share build outputs across different machines, further reducing build times. To set up a remote build cache, you need a server that supports HTTP caching. Gradle provides a built-in HTTP build cache that you can use.

Here’s a basic example of how to configure it:

buildCache {
    remote(HttpBuildCache) {
        url = 'https://my-build-cache-server/cache/'
        credentials {
            username = 'user'
            password = 'password'
        }
        enabled = true
    }
}

Ensure that your cache server is properly configured to handle requests. You can use tools like Apache or Nginx to set up your caching server.

1. What is the difference between local and remote build caches?

Local build caches store outputs on the developer's machine, while remote build caches store outputs on a shared server accessible by multiple developers. Remote caches are beneficial for teams to avoid redundant builds.

2. How can I see what is being cached?

You can enable Gradle's debug logging by using the flag --info or --debug to view cache hits and misses during the build process.

3. Can I configure the build cache for specific tasks only?

Yes, you can configure individual tasks to be cacheable by explicitly defining their inputs and outputs, as shown in previous examples.

4. What happens if my build cache server goes down?

If your remote build cache server is unavailable, Gradle will fall back to using the local cache. However, if the local cache is empty, it will execute all tasks normally.

5. Are there security concerns with using a remote build cache?

Yes, ensure your remote build cache is secured with HTTPS and proper authentication to prevent unauthorized access to cached outputs.

To effectively utilize Gradle's build cache, follow these best practices:

  • Regularly clean and maintain your build cache to prevent it from growing excessively large.
  • Monitor build performance metrics to identify bottlenecks and optimize further.
  • Keep your build scripts modular to improve cache efficiency.

Gradle is continuously evolving, with new features and improvements being added regularly. The community is actively working on enhancing build caching capabilities, including better support for complex build scenarios and improved performance metrics. Staying updated with the latest releases and participating in community discussions can help you take advantage of these advancements.

Leveraging Gradle's build cache is a powerful way to enhance performance in large projects. By understanding how the build cache works, configuring it properly, and following best practices, you can significantly reduce build times and improve developer productivity. As Gradle continues to evolve, keeping abreast of new features will further enhance your build processes and project efficiency. Start implementing these techniques today and experience the performance benefits for yourself!

PRODUCTION-READY SNIPPET

When dealing with Gradle's build cache, developers may encounter common pitfalls that can undermine performance gains. Here are some challenges and their solutions:

1. Cache Invalidation

Cache invalidation occurs when a task's inputs change, causing a rebuild. To mitigate this, ensure that your inputs and outputs are correctly defined to avoid unnecessary cache misses.

2. Task Dependency Misconfiguration

Incorrectly configured task dependencies can lead to redundant executions. Always review task dependencies to ensure they are appropriately set up.

3. Side Effects in Tasks

Tasks that produce side effects can lead to unpredictable cache behavior. Always strive to make tasks idempotent, meaning they can be executed multiple times without changing the result beyond the initial application.

⚠️ Warning: Misconfigured tasks can lead to significant performance degradation. Regularly audit your build scripts for best practices.
PERFORMANCE BENCHMARK

While enabling the build cache is a significant step toward improving build performance, there are additional strategies you can implement. Here are some tips:

  • Use Configuration on Demand: This feature only configures projects that are necessary for the current task, reducing memory usage and configuration time.
  • Parallel Builds: Enabling parallel builds allows independent projects to be built simultaneously, speeding up the overall build process.
  • Incremental Builds: Gradle supports incremental builds, meaning it only rebuilds parts of the project that have changed.
Open Full Snippet Page ↗
SNP-2025-0468 Twig code examples programming Q&A 2026-04-26

How Can You Leverage Twig's Extensibility for Powerful Web Templates?

▾
THE PROBLEM

In the world of web development, templating engines have become essential for separating logic from presentation. Among these, Twig stands out due to its flexibility, readability, and powerful features. But how can developers leverage Twig's extensibility to create robust and maintainable web templates? This question is crucial as understanding Twig's extensibility can greatly enhance how developers build their applications, allowing for better code organization, reusability, and performance.

Twig was created by Fabien Potencier, the founder of Symfony, to provide a modern templating engine for PHP. Released in 2010, it aimed to offer a more secure and efficient way to design templates compared to traditional PHP file inclusions. Twig's syntax is clean and concise, allowing developers to create templates quickly without compromising on functionality. As web applications have evolved, so too has the need for powerful templating solutions, making Twig a go-to choice for many frameworks, including Symfony, Laravel, and others.

At its core, Twig uses a simple, clean syntax that emphasizes readability. Here are some of the key features that make Twig an attractive choice for developers:

  • Separation of Concerns: Twig allows developers to separate HTML from PHP logic, making templates easier to read and maintain.
  • Security: It auto-escapes variables to prevent XSS attacks, making it a secure choice for web applications.
  • Extensibility: Developers can create custom filters, functions, and tags to extend Twig's capabilities.
  • Performance: Twig compiles templates down to optimized PHP code, which can significantly improve performance.

One of the most powerful features of Twig is its extensibility through custom filters. Filters allow you to modify variables in your templates easily. Here’s how you can create a custom filter:


// src/Twig/AppExtension.php
namespace AppTwig;

use TwigExtensionAbstractExtension;
use TwigTwigFilter;

class AppExtension extends AbstractExtension
{
    public function getFilters()
    {
        return [
            new TwigFilter('reverse', [$this, 'reverseString']),
        ];
    }

    public function reverseString($string)
    {
        return strrev($string);
    }
}

To use this filter in your Twig template, you can simply call it as follows:


{{ 'Hello, World!'|reverse }}

This would output: !dlroW ,olleH

Just like filters, you can create custom functions to encapsulate reusable logic. Here’s an example of how to create a custom function in Twig:


// src/Twig/AppExtension.php
public function getFunctions()
{
    return [
        new TwigFunction('current_year', [$this, 'getCurrentYear']),
    ];
}

public function getCurrentYear()
{
    return date('Y');
}

Now you can use this function in your template:


Current Year: {{ current_year() }}

Custom tags are another way to extend Twig's functionality. Tags allow you to introduce new syntax into your templates. Here's how to create a simple custom tag:


// src/Twig/AppExtension.php
use TwigTokenParserAbstractTokenParser;
use TwigToken;

class MyCustomTag extends AbstractTokenParser
{
    public function parse(Token $token)
    {
        // Parse the tag
    }

    public function getTag()
    {
        return 'my_custom_tag';
    }
}

This example sets the groundwork for building more complex logic around your custom tags. You would then register this custom tag in your extension for it to be recognized in your templates.

💡 Best Practice: When creating custom filters, functions, or tags, ensure they are reusable and maintainable. Avoid tightly coupling them to specific templates.

Here are some best practices to keep in mind:

  • Keep custom logic outside of templates to maintain the separation of concerns.
  • Document your custom extensions to ensure that other developers can easily understand their purpose and usage.
  • Test your custom filters and functions thoroughly to prevent unexpected behavior in templates.

Security is paramount in web development. Here are some security best practices when using Twig:

  • Always Enable Auto-Escaping: Auto-escaping is enabled by default in Twig, which helps prevent XSS attacks. Ensure it remains enabled in your Twig configuration.
  • Sanitize User Input: Always validate and sanitize user inputs before using them in your templates.
  • Use Secure Functions: When creating custom functions, ensure they do not expose sensitive information or allow execution of arbitrary code.

Understanding how Twig fits within popular frameworks can provide insight into its capabilities. Here’s a brief comparison:

Framework Templating Engine Strengths
Symfony Twig Highly integrated, secure, performance-focused
Laravel Blade Easy syntax, includes features like template inheritance
CodeIgniter PHP-based Less overhead, straightforward for beginners

1. What are the main advantages of using Twig over plain PHP for templating?

Twig offers a cleaner syntax, built-in security features like auto-escaping, and powerful extensibility, which makes it easier to maintain and develop complex applications compared to plain PHP.

2. Can I use Twig outside of a framework?

Yes, Twig can be used independently. You can install it via Composer and use it within any project that requires templating.

3. How does Twig compare to other templating engines like Mustache or Handlebars?

While Mustache and Handlebars are logic-less templating engines focusing on simplicity, Twig provides more advanced features, including custom filters and tags, making it suitable for complex applications.

4. Is it possible to compile Twig templates?

Yes, Twig compiles templates into PHP code for improved performance. This compilation step is handled automatically and can be configured in your Twig settings.

5. What should I do if I encounter performance issues with Twig?

Consider enabling template caching, optimizing your template structure with inheritance, and reviewing your use of custom filters and functions for performance bottlenecks.

Leveraging Twig's extensibility can transform your templating experience, allowing you to build powerful and maintainable web applications. By understanding and implementing custom filters, functions, and tags, you can enhance the functionality of your templates significantly. Coupled with best practices in performance and security, Twig offers a robust environment for modern web development. As you continue to explore its capabilities, you'll find that Twig not only meets your needs but also empowers you to create exceptional web experiences.

PRODUCTION-READY SNIPPET

As with any programming tool, developers may encounter issues while working with Twig. Here are some common errors and their solutions:

  • Error: Variable "foo" does not exist
    Solution: Ensure that the variable has been passed to the template. Check your controller or context to ensure the variable is defined.
  • Error: Unexpected token "name"
    Solution: This usually indicates a syntax error in your Twig template. Double-check your syntax, especially in custom tags and filters.
  • Error: Function "some_function" not found
    Solution: Make sure your custom function is registered correctly in your Twig extension and that the extension is loaded in your application.
PERFORMANCE BENCHMARK

Performance is critical in web applications, and Twig provides several strategies for optimizing template rendering:

  • Caching: Use Twig's built-in caching mechanisms. This can significantly reduce loading times when templates do not change frequently. You can enable caching in your Twig configuration.
  • Template Inheritance: Leverage Twig’s template inheritance feature to avoid redundant code. This allows you to create a base template and extend it in child templates.
  • Minification: Consider minifying your templates to reduce file size and speed up loading times.
Open Full Snippet Page ↗
SNP-2025-0403 Nand2tetris hdl code examples Nand2tetris hdl programming nand2tetris-hdl 2026-04-26

How Can You Effectively Utilize Nand2tetris HDL for Building Complex Digital Circuits?

▾
THE PROBLEM

Nand2tetris is a unique educational project designed to teach the fundamentals of computer science and engineering through the creation of a fully functional computer from the ground up. One of the most fascinating aspects of this project is the Hardware Description Language (HDL) used to define the behavior and structure of digital circuits. Understanding how to utilize Nand2tetris HDL effectively is crucial for anyone looking to deepen their knowledge in digital design and computer architecture.

This blog post will explore various dimensions of Nand2tetris HDL programming, including its core concepts, practical implementations, advanced techniques, and common pitfalls. By the end, you’ll have a comprehensive understanding of how to leverage HDL for building complex digital circuits.

Nand2tetris HDL is a simple yet powerful hardware description language used in the Nand2tetris project. It allows users to describe the behavior of digital circuits in a textual format, which can then be simulated and synthesized into actual hardware components. The language focuses on combinatorial and sequential logic design, enabling users to create a wide range of circuits, from simple gates to complex processors.

💡 Key Features of Nand2tetris HDL:
  • Easy to learn and use, making it accessible for beginners.
  • Supports both combinatorial and sequential logic.
  • Allows for modular design through the use of chips.
  • Integrates seamlessly with the Nand2tetris software suite.

The Nand2tetris project, conceived by Noam Nisan and Shimon Schocken, aims to bridge the gap between theory and practice in computer science education. By building a computer from NAND gates to a high-level programming language, students gain insights into how computers operate at a fundamental level. The HDL is a critical component of this project, allowing users to describe the hardware components in a structured way.

To effectively use Nand2tetris HDL, it’s essential to understand several core concepts:

  • Gates: The basic building blocks of digital circuits, such as AND, OR, NOT, NAND, NOR, etc.
  • Chips: HDL files that encapsulate a specific functionality, which can be reused across projects.
  • Modules: A collection of chips that work together to perform a more complex task.
  • Simulation: The process of testing your HDL code to ensure it behaves as expected before synthesizing it into hardware.

Once you are comfortable with basic HDL concepts, you can start building more complex circuits. For instance, let’s create a 4-bit binary adder using HDL. This involves designing a full adder and then cascading it for multiple bits:


// 1-bit Full Adder
CHIP FullAdder {
    IN a, b, carryIn;
    OUT sum, carryOut;

    PARTS:
    // Logic gates to compute sum and carry
    Xor(a=a, b=b, out=sum1);
    Xor(a=sum1, b=carryIn, out=sum);
    And(a=a, b=b, out=carry1);
    And(a=sum1, b=carryIn, out=carry2);
    Or(a=carry1, b=carry2, out=carryOut);
}

By using this `FullAdder` chip, you can now create a 4-bit adder by instantiating it multiple times and managing the carry bits between them.

While HDL is primarily focused on hardware design, security considerations are still vital. Here are some best practices:

  • Input Validation: Ensure that inputs to your chips are validated to prevent unexpected behavior in your circuits.
  • Documentation: Always document your HDL code clearly. This helps others understand your design and maintain it in the future.
  • Testing: Rigorous testing ensures that your designs function correctly under all expected conditions.

Here are some common questions about Nand2tetris HDL programming:

1. What is the difference between combinatorial and sequential logic in HDL?

Combinatorial logic circuits produce outputs solely based on the current inputs, while sequential logic circuits have memory elements that store previous states, affecting current outputs.

2. Can I use HDL for real-world applications?

While Nand2tetris HDL is primarily educational, the concepts learned can be applied to real-world applications. However, for production systems, more robust HDL languages like VHDL or Verilog are recommended.

3. How can I debug my HDL code?

Utilize the built-in simulation tools provided in the Nand2tetris software suite. You can trace signal values and check for correctness.

4. Are there libraries available for Nand2tetris HDL?

While Nand2tetris HDL does not have extensive libraries like other programming languages, you can create and reuse your chips to modularize your designs effectively.

5. What resources are available for learning more about Nand2tetris HDL?

The official Nand2tetris website offers a comprehensive set of materials, including a textbook, course videos, and forums for community support.

If you’re new to Nand2tetris HDL, here’s a quick-start guide:

  1. Set Up Your Environment: Download the Nand2tetris software suite and familiarize yourself with its interface.
  2. Start Simple: Write your first HDL code for basic gates like AND, OR, and NOT.
  3. Experiment: Modify existing chips to understand how changes affect circuit behavior.
  4. Build Up: Gradually move on to more complex circuits like multiplexers and adders.
  5. Test and Debug: Use the simulation tools to test your designs thoroughly.

Mastering Nand2tetris HDL opens up a world of possibilities in digital circuit design. By understanding its core concepts, implementing practical examples, and avoiding common pitfalls, you can effectively utilize HDL for building complex systems. The journey from simple gates to advanced processors showcases the fundamental principles of computer architecture, laying the groundwork for future explorations in hardware development. Embrace the challenge, and you will find the experience rewarding and enlightening!

PRODUCTION-READY SNIPPET

As with any programming language, there are common pitfalls when working with Nand2tetris HDL. Here are some frequent mistakes and their solutions:

⚠️ Common Pitfalls:
  • Improper Chip Connections: Ensure that all inputs and outputs are correctly connected. Miswiring can lead to unexpected behavior.
  • Ignoring Simulation Results: Always simulate your circuits before synthesizing them. This helps catch logical errors early.
  • Overcomplicating Designs: Keep designs modular and simple to avoid confusion. Break complex functionalities into smaller chips.
REAL-WORLD USAGE EXAMPLE

Let’s start with a simple example of how to write HDL code for a basic AND gate. The following code snippet demonstrates the syntax and structure of an HDL file:


// AND Gate Implementation
CHIP And {
    IN a, b;
    OUT out;

    PARTS:
    // Using Nand gate to create And functionality
    Nand(a=a, b=b, out=nandOut);
    Not(in=nandOut, out=out);
}

This code defines a chip called `And`, which takes two inputs and produces one output. It cleverly uses a NAND gate to implement the AND functionality.

PERFORMANCE BENCHMARK

Optimizing your HDL code can lead to better performance and resource utilization. Here are some techniques:

  • Minimize Gate Usage: Try to use fewer gates by combining functionalities whenever possible.
  • Reduce Path Delays: Design your circuits to minimize the delay between inputs and outputs by optimizing the gate arrangements.
  • Use Hierarchical Design: Break down complex circuits into smaller, manageable chips to improve readability and maintainability.
Open Full Snippet Page ↗
SNP-2025-0026 SQL 2026-04-26

Unlocking the Power of SQL: An In-Depth Interview on Programming with SQL

▾
THE PROBLEM

--- ## Introduction SQL (Structured Query Language) is the backbone of data manipulation and retrieval in relational database management systems. As businesses increasingly rely on data-driven decisions, understanding SQL becomes essential for programmers, analysts, and data scientists alike. In this interview-style blog post, we delve deep into SQL programming, addressing the most pressing questions that both beginners and experienced users might have. ## Getting Started ### What is SQL, and why is it important? SQL, or Structured Query Language, is…

Open Full Snippet Page ↗
SNP-2025-0298 Brainfuck Brainfuck programming code examples 2026-04-26

How Can You Effectively Navigate the Challenges of Writing and Debugging Brainfuck Code?

▾
THE PROBLEM

Brainfuck is a minimalist programming language that, despite its simplicity, poses unique challenges and complexities for developers. Its eight commands and memory manipulation capabilities can lead to convoluted code that is difficult to write, read, and debug. But why should anyone care about such an esoteric language? Understanding Brainfuck not only hones your programming skills but also provides insights into how languages operate at a lower level. This post aims to explore effective strategies for writing and debugging Brainfuck code, delving into its historical context, core technical concepts, and practical implementation details.

Brainfuck was created in 1993 by Urban Müller as a challenge to design the smallest Turing-complete programming language. Its design was meant to be a joke but has since garnered a cult following among programmers and hobbyists. The language uses only eight commands, making it a fascinating study in code efficiency and logic. Understanding its background can provide insight into why the design is so minimalistic and the challenges it presents.

Brainfuck operates on an array of memory cells (often initialized to zero) and a data pointer that points to the current cell. The eight commands are:

  • +: Increment the value at the data pointer.
  • -: Decrement the value at the data pointer.
  • >: Move the data pointer to the right.
  • <: Move the data pointer to the left.
  • .: Output the character at the data pointer.
  • ,: Input a character and store it at the data pointer.
  • [: Jump forward to the command after the matching `]` if the cell at the data pointer is zero.
  • ]: Jump back to the command after the matching `[` if the cell at the data pointer is non-zero.

This limited set of commands can lead to very complex operations, making it challenging to manage state and control flow in programs.

Debugging Brainfuck can be particularly challenging due to its obscure nature. Here are some effective techniques:

  • Visual Debuggers: Use online Brainfuck interpreters that offer a visual representation of memory and pointer positions.
  • Print Debugging: Modify your code to output the memory cell values at various points to understand what's happening.
  • Unit Tests: Create small sections of code that can be tested individually to isolate issues.

By systematically isolating parts of your code and testing them, you can identify where things go awry more efficiently.

Once you have mastered the basics, you may want to optimize your Brainfuck code. Here are some advanced techniques:

  • Loop Unrolling: Simplifying loops can reduce the number of commands executed. This is especially useful for repetitive tasks.
  • Memory Management: Use fewer memory cells by reusing them effectively, thus reducing the complexity of pointer movements.
  • Command Compression: Combine commands where possible. For example, multiple increments can be combined into a single command sequence.

Optimized code not only runs faster but also can be easier to read and understand.

To write effective Brainfuck code, consider the following best practices:

⚠️ Always comment your code for future reference, even if it seems trivial.
  • Commenting: Given Brainfuck’s obfuscation, comments are essential for maintaining readability.
  • Modular Code: Break your code into manageable sections or functions, especially for larger programs.
  • Use Emulators: Test your code in environments that emulate Brainfuck behavior closely to avoid discrepancies.

Following these practices will facilitate easier debugging and enhance code quality.

While Brainfuck is not typically used for production-level applications, it's still important to consider security when writing code:

  • Input Handling: Be cautious with the , command; ensure inputs are validated to prevent unexpected behavior.
  • Memory Leaks: Although rare, improper memory management can lead to unintended memory usage, especially in larger programs.

While Brainfuck is generally safe due to its limited scope, these considerations can help you write more robust applications.

1. What are the practical uses of Brainfuck?

Brainfuck is primarily used for educational purposes, teaching concepts of low-level programming, and as a challenge among programmers. It's not suitable for real-world applications due to its inefficiency.

2. Is Brainfuck Turing complete?

Yes, Brainfuck is Turing complete, meaning it can theoretically perform any computation that can be done by a Turing machine, given enough time and memory.

3. How do I run Brainfuck code?

You can run Brainfuck code using various online interpreters or by installing a local interpreter. Simply paste your code into the interpreter and execute it to see the output.

4. Why is Brainfuck so difficult to read?

The language's minimalistic design, which uses only eight commands, makes it hard to understand and debug. The lack of traditional programming constructs like variables and functions adds to this difficulty.

5. Can I write complex algorithms in Brainfuck?

While it is possible to implement complex algorithms in Brainfuck, doing so is often impractical due to the language's limitations. It is best suited for simple tasks or educational purposes.

Brainfuck, while daunting at first glance, offers a unique opportunity to explore the intricacies of programming languages. By mastering its commands, understanding its memory model, and employing effective debugging and optimization techniques, you can navigate the challenges of writing Brainfuck code. As you delve deeper into this esoteric language, you will not only improve your problem-solving skills but also gain a greater appreciation for how programming languages function at a fundamental level. So, take the plunge and unleash your creativity in the fascinating world of Brainfuck programming!

PRODUCTION-READY SNIPPET

When writing Brainfuck code, several common pitfalls can arise:

Tip: Always keep track of your memory pointer movements. Losing track can lead to unexpected behavior.
  • Pointer Misalignment: If you accidentally move your pointer too far left or right, you may end up manipulating the wrong memory cell.
  • Loop Errors: Misbalanced brackets can create infinite loops or cause your program to terminate prematurely.
  • Memory Overflow: Brainfuck typically uses an array of bytes (0-255). Incrementing beyond this range can cause wrap-around behavior.

To debug these issues, consider using Brainfuck interpreters that provide step-by-step execution, allowing you to monitor pointer movements and memory changes in real-time.

REAL-WORLD USAGE EXAMPLE

To start programming in Brainfuck, let's write a simple program that outputs "Hello World!". Here’s how it looks:


+[----->+++<]>.++++++++..+++.>+++++++++++.>+++++++++++.>+++++++++++.>++++++++.--------.>++++.>++++++++++.

This program is a series of increments and pointer movements that sets up the ASCII values for "Hello World!" in the memory cells. As you can see, writing even simple programs requires a deep understanding of how memory and pointers interact in Brainfuck.

PERFORMANCE BENCHMARK

Performance optimization is crucial, especially when dealing with larger Brainfuck programs. Here are some strategies:

  • Minimize Pointer Movements: Each movement incurs a cost. Try to minimize unnecessary movements to enhance program speed.
  • Batch Operations: Group operations that can be done together to reduce the number of commands.
  • Efficient Loop Usage: Utilize loops wisely to handle repetitive tasks more efficiently.

By employing these techniques, you can write Brainfuck programs that execute faster and are more efficient in terms of memory usage.

Open Full Snippet Page ↗
SNP-2025-0217 Autohotkey Autohotkey programming code examples 2026-04-25

How Can You Leverage Autohotkey for Complex Automation Tasks in Windows?

▾
THE PROBLEM

Autohotkey (AHK) is an incredibly powerful scripting language for Windows that allows users to automate repetitive tasks, create custom keyboard shortcuts, and manipulate windows easily. As the demand for automation grows in various fields, understanding how to leverage AHK for complex automation tasks can significantly increase productivity. In this blog post, we will explore various aspects of using Autohotkey for advanced automation, including its core concepts, practical implementations, best practices, and common pitfalls.

Autohotkey is a free scripting language specifically designed for automating the Windows GUI, but it also offers features for creating simple applications. It was created by Chris Mallett in 2003 and has since gained a robust community and extensive documentation. AHK scripts are easy to write and can perform a wide range of tasks, from simple hotkeys to complex GUI applications.

Did You Know? Autohotkey scripts can be compiled into standalone executables, making it easy to share automation tools without requiring users to install Autohotkey.

Before diving into complex automation tasks, it’s essential to grasp some core concepts of Autohotkey:

  • Hotkeys: Trigger actions with keyboard shortcuts.
  • Hotstrings: Expand abbreviations into longer text or commands.
  • Variables: Store data to be used later in the script.
  • Functions: Reusable blocks of code that can be called with parameters.
  • Control Commands: Interact with GUI elements, such as buttons and text fields.

For those just starting, here’s a quick guide to creating your first AHK script:

; Simple AHK Script
#NoEnv  ; Recommended for performance and compatibility with future AutoHotkey releases.
SendMode Input  ; Recommended for new scripts due to its superior speed and reliability.

; Hotkey: Win + N to open Notepad
#n::
Run Notepad
return

Save the above code with a .ahk extension and double-click it to run. Press Win + N to open Notepad instantly. This illustrates how easy it is to create a simple automation script.

Once you’re comfortable with basic scripts, you can explore more advanced techniques. Here’s an example that automates filling out a form:

; Automate form filling
#Persistent
SetTitleMatchMode, 2

; Hotkey: Ctrl + Shift + F to fill form
^+f::
IfWinExist, Form Title
{
    WinActivate
    Sleep, 200
    Send, John Doe
    Send, {Tab}
    Send, johndoe@example.com
    Send, {Tab}
    Send, 1234567890
    ; Submit the form
    Send, {Enter}
}
return

This script activates a window titled “Form Title”, fills in a name, email, phone number, and submits it. This demonstrates how AHK can interact with application windows directly.

To write effective and maintainable AHK scripts, consider the following best practices:

Tip: Always comment your code to explain the purpose of complex actions. This will help you (or others) understand the script later.
  • Use Descriptive Variable Names: This enhances readability and maintainability.
  • Break Down Larger Scripts: Modularize your code by creating functions for distinct tasks.
  • Test Incrementally: Run your script frequently during development to catch errors early.

While AHK is a powerful tool for automation, security should be a priority. Here are some security best practices:

  • Validate Input: Ensure any user input is validated to prevent injection attacks.
  • Limit Script Permissions: Avoid running scripts with administrator privileges unless necessary.
  • Keep Scripts Private: Do not share sensitive scripts that contain personal information or credentials.

Autohotkey continues to evolve, with new features and enhancements being added regularly. Some areas to watch for future developments include:

  • Improved GUI Capabilities: Enhancements to the GUI library for creating more complex UIs.
  • Cross-Platform Support: While AHK is primarily for Windows, discussions are ongoing about potential support for other operating systems.

1. Can Autohotkey run on Mac or Linux?

No, Autohotkey is designed specifically for Windows. However, you can use Wine to run AHK scripts on Linux, but functionality may be limited.

2. How do I troubleshoot my AHK scripts?

Use the built-in debugging tools, such as MsgBox to display variable values or statuses at various points in your script.

3. What are the best resources to learn AHK?

The official Autohotkey documentation, forums, and community tutorials are excellent resources for learning and troubleshooting.

4. Can AHK interact with web applications?

Yes, AHK can automate web applications using the ControlSend and Send commands, although interactions may vary based on the browser.

5. Is Autohotkey suitable for large-scale automation?

Yes, AHK can handle large-scale automation tasks, but for very complex systems, consider using it in conjunction with other programming languages or frameworks.

Autohotkey is a versatile and powerful tool for automating complex tasks in Windows. By mastering its core concepts and applying advanced techniques, developers can significantly boost productivity and efficiency. As you continue to explore AHK, remember to follow best practices, stay aware of security considerations, and keep an eye on future developments. With the right knowledge and approach, you can leverage Autohotkey to streamline your daily workflows and enhance your work processes.

PRODUCTION-READY SNIPPET

Even the best scripts can encounter errors. Here are some common error codes in Autohotkey and how to address them:

Error Code Description Solution
0x1 Invalid parameter Check the function or command syntax for errors.
0x2 File not found Ensure the file path is correct and accessible.
0x3 Access denied Run AHK with administrator privileges if required.
PERFORMANCE BENCHMARK

When dealing with complex automation tasks, performance can become an issue. Here are some techniques to optimize your AHK scripts:

  • Minimize Sleep Commands: Excessive use of the Sleep command can slow down your script. Only use it when necessary.
  • Use ControlSend: This command sends keystrokes directly to a window, which can improve performance.
  • Limit GUI Interactions: Reducing the number of GUI interactions can enhance speed. Use direct memory manipulation when possible.
Open Full Snippet Page ↗
SNP-2025-0362 Inform7 code examples Inform7 programming 2026-04-25

How Can You Utilize Advanced Features of Inform7 to Create Engaging Interactive Fiction?

▾
THE PROBLEM
In the realm of interactive fiction (IF), Inform7 stands out as a powerful language that allows writers to craft immersive narratives in a natural language format. This question explores how you can harness the advanced features of Inform7 to create engaging stories that captivate players. Understanding these features is crucial for developing complex interactive worlds that respond meaningfully to player actions, thereby enhancing the overall gaming experience. Inform7 provides a unique blend of programming and narrative design. Its syntax allows authors to write code that reads almost like English, making it accessible for those without a strong programming background. However, to truly create compelling interactive fiction, one must delve deeper into its advanced capabilities. Throughout this post, we will explore various techniques, best practices, and practical code snippets to elevate your Inform7 projects. Inform7 has its roots in the earlier versions of the Inform programming language, which were primarily designed for creating text-based games. Released in 2006, Inform7 introduced a new programming paradigm that emphasized natural language syntax. This shift has allowed a broader audience, including writers and game designers, to engage in interactive storytelling without needing extensive programming knowledge. The evolution of Inform7 reflects a wider trend in game development, where narrative depth and player agency are increasingly prioritized. Understanding the historical context and the development of Inform7 can enhance your appreciation of its capabilities and inspire you to leverage its features effectively. At the heart of Inform7 are several core concepts that are fundamental to creating interactive fiction: 1. **Story Structure**: Inform7 operates on a story-based model where the world is defined through rooms, objects, and characters. Understanding how to structure these elements is vital for creating an engaging narrative. 2. **Actions and Responses**: Players can perform actions that affect the game's world. Defining how these actions interact with objects and characters can lead to intricate storylines. 3. **Rules and Conditions**: Inform7 allows the creation of rules that dictate how the game responds to player actions. This feature enables dynamic storytelling where player choices significantly impact the narrative. 4. **Attributes and Properties**: Objects in Inform7 can have various attributes that determine their behavior and interactions. Utilizing attributes effectively can create rich, interactive environments. These concepts form the backbone of the Inform7 language and are essential for creating complex and engaging stories. To create an engaging interactive experience, the setting must be immersive. Here’s how to effectively establish environments in Inform7: 1. **Defining Rooms**: Each location in your game is defined as a room. You can specify descriptions, exits, and connections to other rooms.

Room1 is a room. "You are in a dimly lit cavern. The air is damp and cold."
Room2 is east of Room1. "This room is filled with strange glowing crystals."
2. **Adding Objects**: Populate your rooms with objects that players can interact with. Objects can have descriptions, actions, and even responses to player actions.

A crystal is in Room2. "A mysterious crystal that emits a soft glow."
Instead of examining the crystal:
    say "The crystal vibrates slightly at your touch.";
3. **Dynamic Descriptions**: Use conditions to change room descriptions based on player actions. This technique keeps the environment feeling alive and responsive.

After taking the crystal:
    now Room2 is "This room feels emptier now. The glowing crystal is missing.";
Engaging interactive fiction often involves complex interactions between players and the game world. Here are some techniques to implement these interactions: 1. **Custom Actions**: You can define custom actions that players can perform, allowing for unique gameplay mechanics.

Understand "ignite [something]" as igniting.
Instead of igniting the crystal:
    say "The crystal bursts into flames, illuminating the room.";
2. **Conditional Responses**: Create responses based on the state of the game or player actions to enrich the narrative.

Instead of examining the crystal when it is burning:
    say "The crystal radiates heat, and its glow is blinding.";
3. **Dialogue Systems**: Implementing conversations with characters can enhance storytelling. You can create dialogue trees that allow players to choose responses.

A mysterious figure is in Room1. 
Instead of talking to the figure:
    say "The figure looks at you intently. What do you want to ask?";
    
Instead of asking the figure about "the crystal":
    say "The figure whispers, 'That crystal holds great power.'";
To achieve the best results in your Inform7 projects, consider the following best practices:
💡 Use comments liberally to annotate your code, especially in complex sections.
⚠️ Always test your code regularly to catch bugs early in the development process.
✅ Break down your story into manageable sections to maintain clarity and focus.
1. **Organize Your Code**: Structuring your code logically makes it easier to manage as your story grows. Group related functionalities together. 2. **Maintain Player Agency**: Ensure that players feel their choices matter. This can be achieved by allowing multiple paths and outcomes based on decisions. 3. **Iterative Development**: Start with a basic version of your game and gradually add features and complexity. This approach allows for testing and feedback throughout the development process. While Inform7 is primarily focused on narrative and gameplay, security considerations cannot be ignored, especially if you plan to share your work online. 1. **Input Validation**: Ensure that player inputs do not lead to unintended actions or states within your game.

Understand "use [something]" as using.
Instead of using the crystal:
    if the crystal is not in your possession:
        say "You don't have that!";
    otherwise:
        say "You cannot use the crystal in this way.";
2. **Access Control**: Consider restricting certain features or commands based on game progression to prevent players from breaking the narrative flow. 3. **Error Handling**: Implement error handling to provide users with informative messages when something goes wrong. **Q1: Can I integrate multimedia elements into my Inform7 game?** A: While Inform7 is primarily text-based, you can link to multimedia elements hosted externally. However, native support for images and sound is limited. **Q2: How do I manage complex story branches in Inform7?** A: Use variables to track player choices and create conditions that alter the narrative based on these variables. **Q3: Can I localize my Inform7 stories for different languages?** A: Yes, you can write your story in multiple languages by creating separate versions of your text and using conditions to switch based on player selection. **Q4: What resources are available for learning more about Inform7?** A: The official Inform7 website provides extensive documentation, tutorials, and community forums for support. **Q5: How do I publish my Inform7 game?** A: You can compile your game into an executable format or share it as a web-based application using the Inform7 web compiler. If you’re new to Inform7, here’s a quick-start guide to help you begin your interactive fiction journey: 1. **Download Inform7**: Visit the [Inform7 website](http://inform7.com) to download the software. 2. **Familiarize Yourself with the Interface**: Explore the built-in tutorials and example projects to understand the environment. 3. **Start Small**: Create a simple story with one or two rooms and a few objects. Gradually add complexity as you grow comfortable with the language. 4. **Utilize the Community**: Join forums and communities to learn from experienced authors and share your work for feedback. Creating engaging interactive fiction in Inform7 is an enriching experience that merges technology and storytelling. By leveraging advanced features such as complex interactions, dynamic environments, and solid coding practices, you can develop immersive narratives that resonate with players. Remember to stay organized, test frequently, and embrace player feedback as you refine your story. As you embark on your Inform7 journey, keep experimenting with different techniques and always strive to enhance your storytelling craft. The world of interactive fiction is vast, and with the right tools and mindset, you can create experiences that captivate and inspire. Happy coding!
PRODUCTION-READY SNIPPET
When working with Inform7, developers often encounter common pitfalls. Here are some solutions to these issues: 1. **Overly Complex Code**: Avoid writing overly complicated rules that can confuse both the player and the developer. Simplify your logic wherever possible. - **Solution**: Use clear, concise language and break complex actions into smaller, manageable pieces. 2. **Lack of Testing**: Not testing frequently can lead to significant debugging challenges later. - **Solution**: Regularly compile and playtest your game to catch issues early on. 3. **Ignoring Player Feedback**: Failing to consider player feedback can result in a less engaging experience. - **Solution**: Encourage playtesting among peers and be open to criticism to improve your game.
PERFORMANCE BENCHMARK
Optimizing your Inform7 game for performance can enhance the player experience. Here are techniques to consider: 1. **Efficient Object Management**: Limit the number of objects and keep your code organized. This reduces memory usage and improves performance.

Instead of taking all:
    say "You can't carry everything at once.";
2. **Minimize Heavy Computation**: Avoid placing heavy computations in frequently called rules or actions to prevent lags. 3. **Use Variables Wisely**: Utilize variables to store information temporarily instead of creating too many global states. - Example of a variable usage:

Instead of examining the crystal:
    increase the crystal's temperature by 1;
Open Full Snippet Page ↗

PAGE 18 OF 47 · 469 SNIPPETS INDEXED