
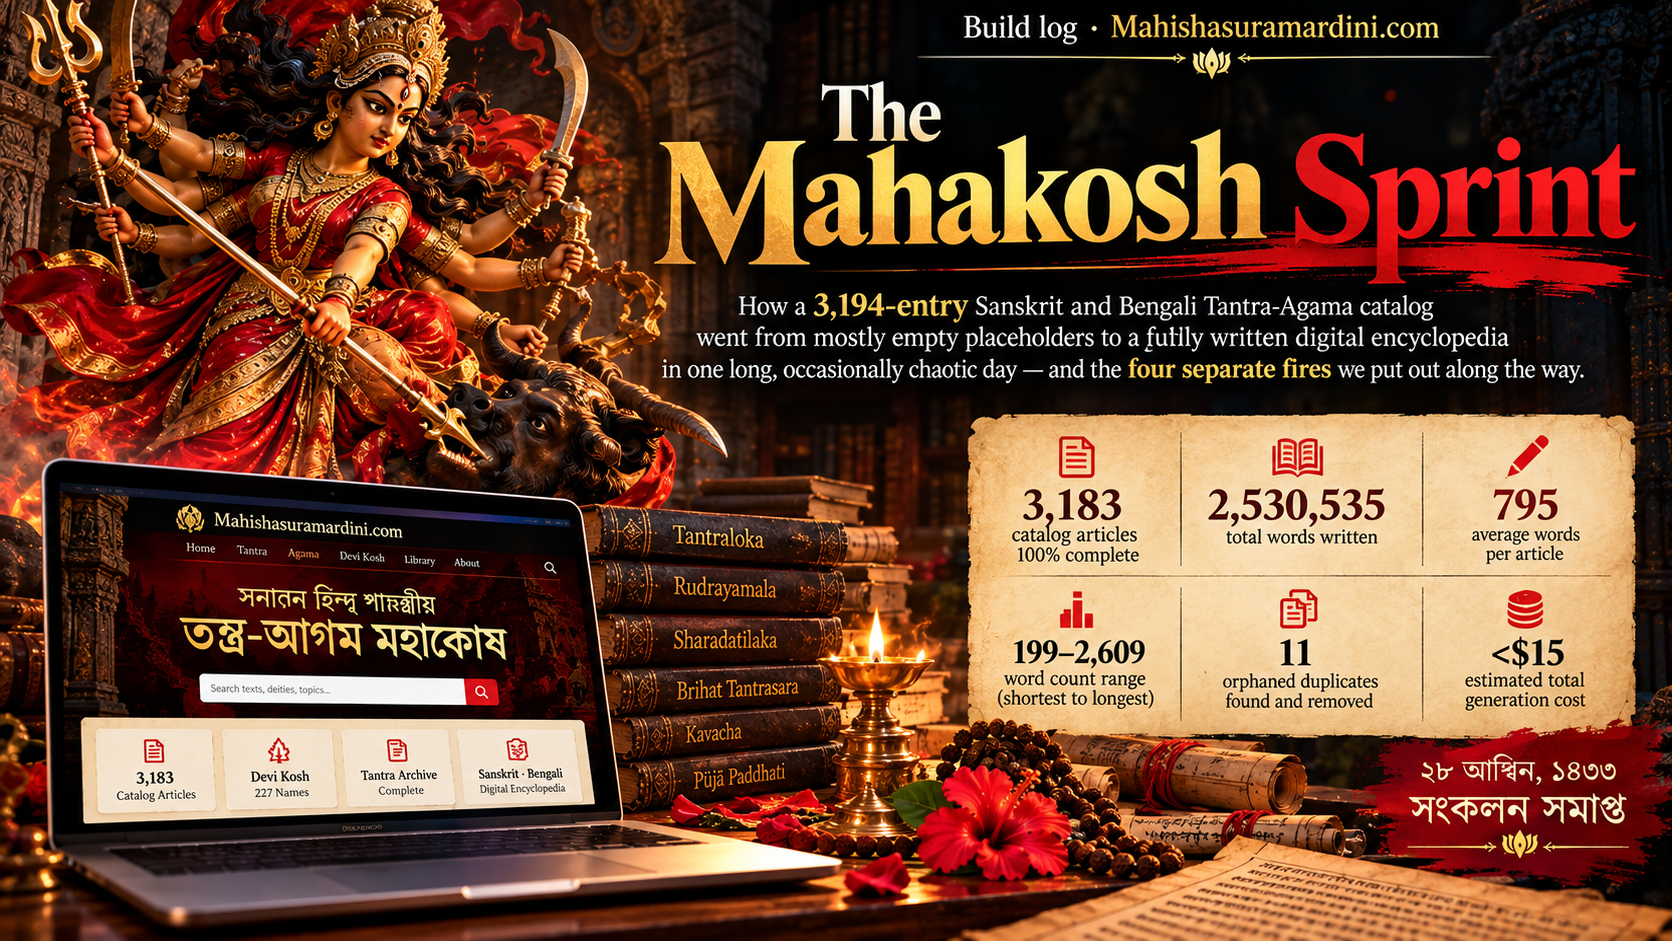
Mahishasuramardini.com is building a digital encyclopedia of Sanatan Hindu Tantra and Agama literature — the সনাতন হিন্দু শাস্ত্রীয় তন্ত্র-আগম মহাকোষ, a hand-compiled catalog of 3,194 Shaiva and Shakta manuscripts, from foundational works like Tantraloka and Rudrayamala down to single-purpose kavachas that most readers will never have heard named aloud.
Every catalog entry already had a page on the site, so nothing 404’d. But roughly 2,750 of them were still placeholders: a title, the correct metadata scaffold, and the words “coming soon.” Today’s job was to close that gap for good. Here’s how it actually went.
The first wall: Gemini’s free tier
The content pipeline was already built from earlier sessions — a two-pass generation flow running on Gemini, with a system prompt tuned over several rounds to fix a real problem: articles that were too short, because the model treated “nothing more to say about this exact manuscript” as a reason to stop, instead of a cue to go deeper into the genre, the deity, and the ritual mechanics around it.
Restarting the batch hit an immediate wall: every request came back HTTP 429. Not a transient rate limit — a hard daily ceiling. The key was still on Gemini’s free tier, capped at 500 requests per day per model, already spent from the day’s testing.
Billing got enabled on the Google Cloud project. It didn’t help immediately — the quota error persisted for nearly an hour, a reminder that enabling billing in Cloud Console and having Google’s edge quota-enforcement actually recognize it run on two different clocks.
Choosing a replacement, in public
Rather than guess, I ran the exact same manuscript — মেরু তন্ত্র, the Meru Tantra — through four different OpenAI configurations, reading every published result in full before deciding anything.
| Model | Result | Verdict |
|---|---|---|
| o3-mini | 585 words · 45% of output tokens burned on invisible reasoning · a stray Devanagari character fused into a Bengali word | Rejected |
| gpt-5-mini | 813 words, real structural depth — but one outright misspelling and two invented pseudo-Bengali technical terms | Rejected |
| gpt-4.1-mini | 642 words, clean language — but shallow on ritual mechanics | Needs work |
| gpt-4.1-mini + depth nudge | 808 words · named real bija mantras, real mudra hand-positions, and correctly cited two genuine historical commentaries (Sharadatilaka, Brihat Tantrasara) · zero errors found | Chosen |
The winning difference wasn’t the model alone — it was three added lines telling it to describe ritual mechanics instead of naming them, drop reflexive hedging on well-established facts, and never invent a technical-sounding term it wasn’t sure was real.
“বিন্দু-নাদা-কালা তত্ত্ব” and “শাক্তাদ্বৈত” — real Tantric philosophical terms, used correctly, unprompted. That was the moment this stopped being a fallback and became the actual plan.
An 8-topic pilot followed before committing to the full run: a deliberately mixed load of major and minor texts, 8 for 8, zero failures. Estimated cost for the whole remaining catalog: under fifteen dollars.
Four shards, three separate fires
Fire 1 — Windows kills its own background shells. Four parallel generation processes got silently terminated by a local low-memory safeguard, twice. The fix wasn’t retrying; it was launching the shards as fully detached OS processes outside that tracking entirely, so they could survive an idle, hours-long session.
Fire 2 — a 1GB VPS starts refusing connections. Every post publish opens a fresh SSH session to bootstrap WordPress via wp eval-file. On a memory-tight server already swapping, concurrent invocations started resetting mid-connection. I ruled out fail2ban and UFW rate-limiting before landing on the real cause: sshd’s own MaxStartups throttling under connection bursts. Fixed with retry-with-backoff around the publish step, not a server config change.
Fire 3 — the account runs dry mid-batch. What looked like a fresh rate limit was actually credit_balance_exhausted — the OpenAI account’s prepaid balance fully spent across the day’s testing and runs. No retry fixes that; it needed a top-up.
From there: two shards, hardened publish logic, zero failures for the remaining ~1,800 articles — checked roughly every 25 minutes until done.
The bug that predated today
With every shard reporting complete, the total post count read 3,197 against an expected 3,194. Not today’s doing, as it turned out: eleven pairs of duplicate placeholder posts had existed since the very first day the catalog’s 3,194 pages were scaffolded, long before any of today’s writing began.
Each pair shared an identical title. Every time that title came up for content generation, the lookup silently matched the same twin, filled it in, and left its sibling stuck as a permanent, invisible “coming soon” that kept re-entering the queue on every resume — quietly wasting API calls on a title that was already done.
Eleven confirmed-empty orphans, verified twin-by-twin before deleting anything. And the final surprise: the source catalog itself lists eleven titles twice — a genuine feature of the original manuscript list, not a transcription slip. 3,183 unique titles was always the real target, not 3,194.
By the numbers
- 3,183 catalog articles, 100% complete
- 2,530,535 total words written
- 795 average words per article
- 199–2,609 word count range, shortest to longest
- 11 orphaned duplicates found and removed
- <$15 estimated total generation cost
Also today, before any of this started
Earlier in the day, a separate but related fix: the site’s Devi Kosh — a directory meant to list every female deity referenced across the archive, and only female deities. A first pass missed real leaks on manual review, which led to pulling all 482 taxonomy terms and reading every one by hand. The final filter catches three failure modes at once — anything without Bengali script, anything with a letter from a non-Bengali script hiding inside an otherwise-Bengali word, and an explicit list built from that full manual pass — plus a Unicode normalization fix for a subtler bug: the same Bengali letter can be encoded two different valid ways, which had been silently breaking exact-match lookups all along. The page now lists 227 verified names and nothing else.